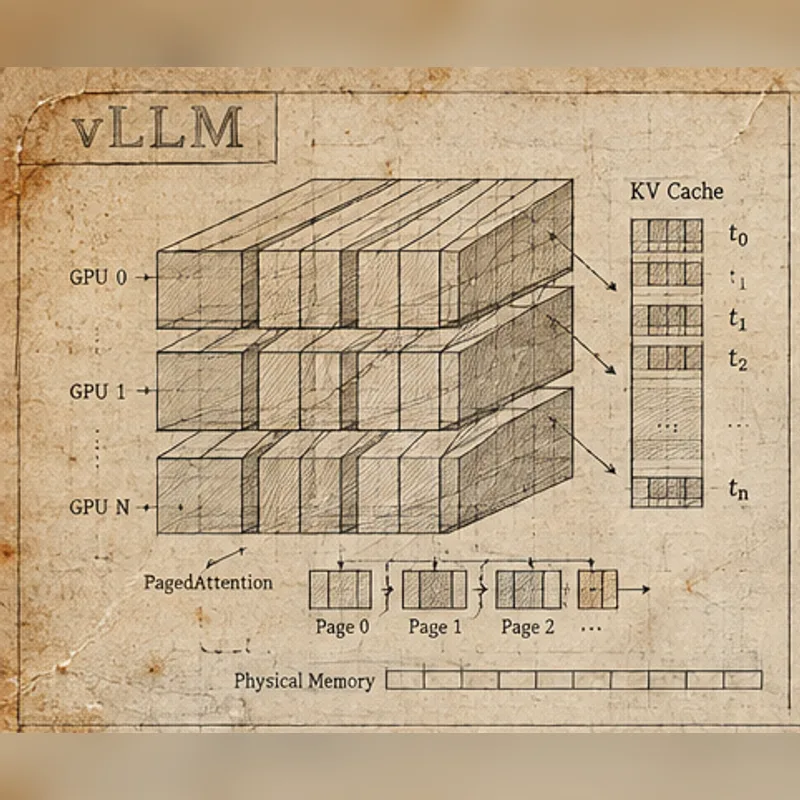
October 2026
vLLM Paper Notes
Simple notes on vLLM and PagedAttention for efficient LLM serving with paged KV cache memory management and sharing.
October 2026
Simple notes on vLLM and PagedAttention for efficient LLM serving with paged KV cache memory management and sharing.
October 2026
Simple notes on DeepSeek V4.1 Flash and how it shrinks KV cache for million token agents while improving quality.
September 2026
A runtime theory for live plugin composition with undoable effects and reactive dependencies, built as Cordis and proven on thousands of Koishi plugins.
September 2026
Michael Levin on hidden patterns that shape bodies and minds, from bioelectric memories and Xenobots to sorting algorithms that act smart.
August 2026
Continual Harness: agents that improve their own tools, skills, and memory mid-run, studied through Pokemon gameplay.
August 2026
RLSVR and SpyRL: turning open-ended tasks into self-verifiable games so models improve without judges or reward models.
July 2026
DeepSeek-V4: making million-token context practical with hybrid compressed attention, hyper-connections, and the Muon optimizer.
July 2026
Why plain OPSD damages long chain-of-thought reasoning, and how purified OPSD preserves reflective epistemic markers.
July 2026
SDPO: self-teacher policy optimization that fixes the sparse credit-assignment bottleneck of RLVR for code and math.
July 2026
GKD: distilling large models into smaller ones by training on student-generated outputs instead of fixed datasets.
June 2026
A ground-up primer: MDPs, TD learning, Q-learning, policy gradients, actor-critic, GAE, and the RL taxonomy.
June 2026
From RLHF pipelines to the PPO clipped objective: why RL follows SFT and how PPO training loops work for language models.
June 2026
OPSD: one model acting as its own teacher and student for better reasoning, using privileged contexts for dense token feedback.
June 2026
Beating catastrophic forgetting with self-distillation fine-tuning that preserves in-context abilities while learning new tasks.
June 2026
Notes on LIFE-HARNESS: fixing the model failures by adapting the runtime interface instead of retraining the model.
June 2026
Do AGENTS.md-style repo context files actually help coding agents? Notes on the paper and its AGENTbench evaluation.
June 2026
CaMeL: system-level security for computer-use agents via a dual-LLM design that separates planning from acting.
June 2026
DeepDive: training open-source deep-research agents with auto-generated hard questions and multi-turn RL.
June 2026
DeepSeekMath: how a 7B open-source model approached GPT-4 math performance, and the GRPO algorithm behind it.
June 2026
DeepSeek-R1: teaching a model to reason through pure RL with no supervised traces, then distilling it into smaller models.
June 2026
Natural-language agent harnesses: writing agent runtime logic as editable text instead of code, and what the experiments show.
June 2026
Recursive Language Models: handling huge contexts by letting the model explore the prompt with code and call itself on pieces.
June 2026
SFR-DeepResearch: the Salesforce recipe for autonomous single-agent deep research via single-turn reformulation and RL.
October 2025
Outcome vs. process reward models in RL training: why rewarding each reasoning step helps, and why steps, annotation, and reward hacking make PRMs hard.
July 2025
Pipeline, tensor, and sequence parallelism for faster LLM inference, and how combining them scales large models to longer inputs.